Model Development & Validation
Purpose-built machine learning models trained and benchmarked against your data — with an architecture chosen because it fits, and validation that holds up against real domain ground truth, not just a leaderboard score.
TYPICAL CLIENT
A data science lead who needs a model that survives contact with real biological data
Usually a Head of Data Science, VP of R&D or ML engineer who has candidate data and a target outcome, but needs the architecture, training approach and validation strategy chosen — and defended — by someone who has done this on noisy, small, high-stakes life-sciences datasets before.
Six concrete deliverables, not a slide deck.
This is exactly what transfers to you at the end of this engagement.
Model architecture selection & justification
A written rationale for why a given model type fits your data and constraints, benchmarked against at least two alternatives.
Reproducible training & validation pipeline
Versioned training code with train/test/holdout splits documented, so results can be regenerated exactly.
Domain ground-truth validation report
Evaluation against real biological or operational outcomes, not just statistical holdout accuracy.
Baseline comparison
A simple baseline model trained alongside the final candidate, so added complexity is proven to earn its keep.
External/holdout validation results
Performance measured on data the model never touched during training or tuning — the number that actually matters.
Full source code & versioned model weights
Everything transfers to you outright: training scripts, configs and every checkpointed weight.
What this service includes
Architecture selection & benchmarking
Multiple candidate architectures trained and compared head-to-head, not just one model shipped on faith.
Cross-validation & holdout design
Splits designed around your actual sources of leakage — by patient, batch or timepoint, not a random shuffle.
Domain ground-truth evaluation
Metrics chosen and reported against the biological or operational outcome the model needs to support.
Model documentation & handoff
A written record of what was tried, what worked, what didn’t, and why — so the decision is auditable later.
What this looks like in a real engagement
Three concrete examples of the kind of work this service covers.
Triage classifier benchmarked against clinician labels
Three candidate architectures trained on the same diagnostic dataset, validated against clinician-reviewed ground truth before one was selected.
Potency regression model validated by held-out compound series
A model tested against compound series excluded entirely from training, to catch performance that looked good only because of chemical similarity leakage.
Drift-resistant model for a shifting instrument pipeline
A model retrained and re-validated as assay instrumentation changed, keeping performance honest as the input data shifted.
Why “validated” has to mean something more than a good accuracy score.
A model can look excellent on a random 80/20 split and fail completely once it meets a new patient cohort, a new instrument batch, or a new lab. In life sciences, the split itself is often the difference between a real result and an illusion of one.
We design validation around the actual ways your model could quietly fail — batch effects, cohort shift, small sample sizes — so the number we report is the number that survives deployment.
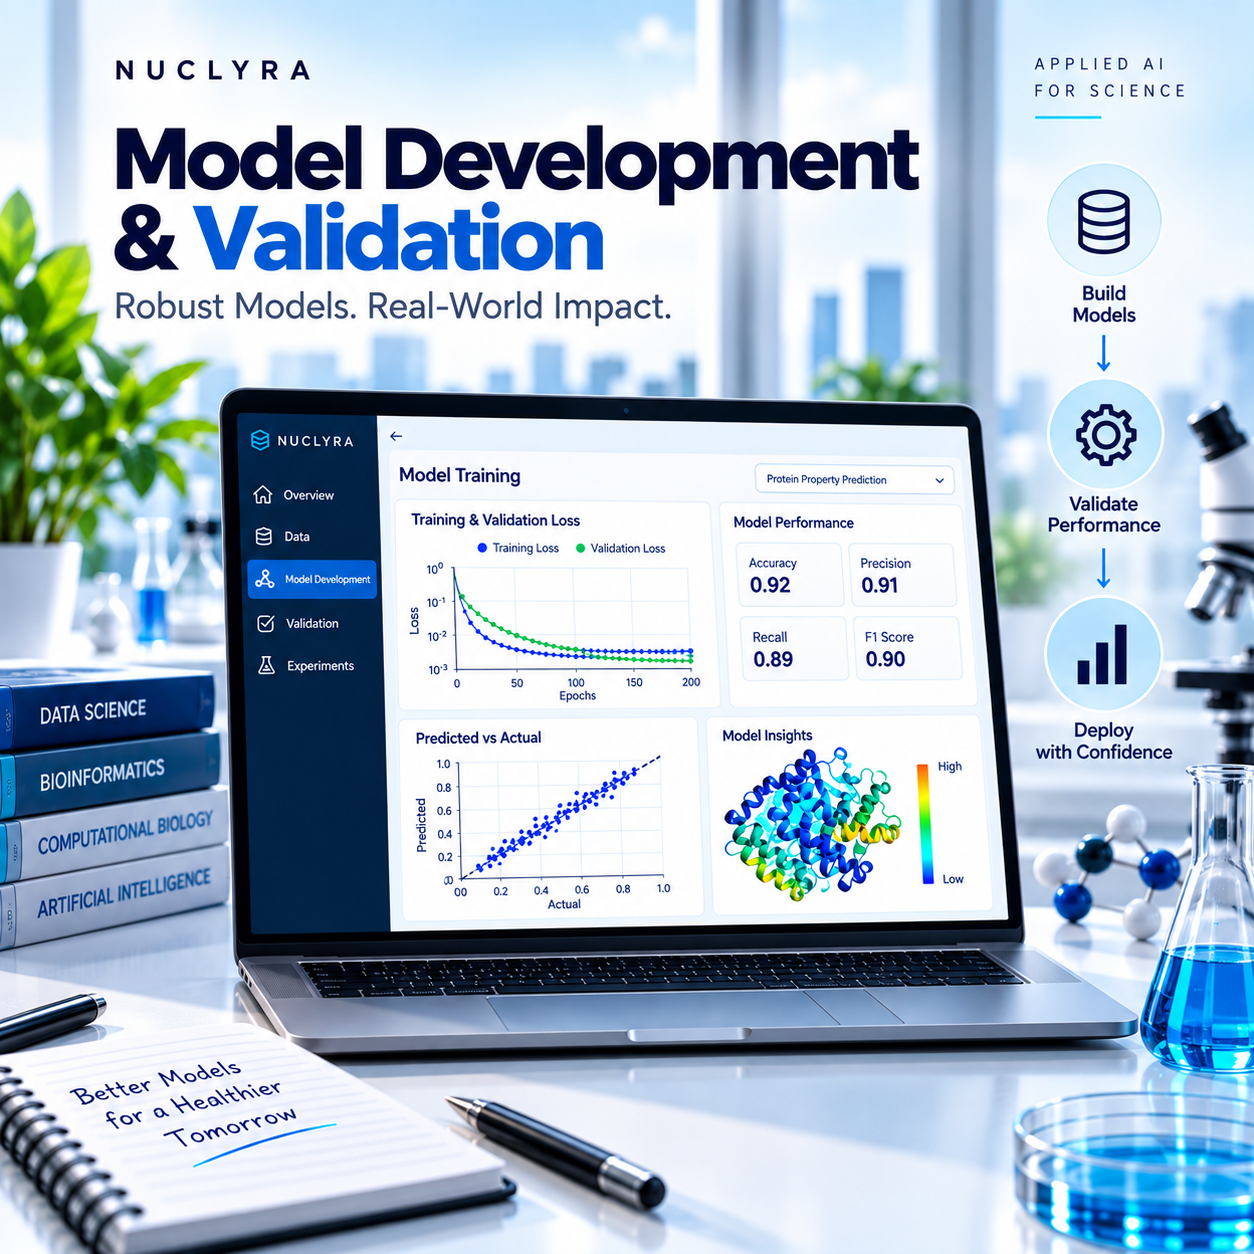
How an engagement runs
Four stages, from initial scope to delivery.
Define the target & baseline
We agree on the outcome the model needs to predict and train a simple baseline first.
Design the validation strategy
Splits are designed around your real sources of leakage, before any serious model training starts.
Train & compare candidates
Multiple architectures are trained and benchmarked against the baseline and each other.
Validate & hand off
Final performance is confirmed on untouched holdout data, then documented and transferred to you.
What we build it with
The architecture we picked wasn’t the most exciting one on paper — it was the one that held up on data it had never seen.
Before you reach out
We start from the simplest model that could plausibly work, then only add complexity that demonstrably improves performance on held-out data.
It depends on your data, but the split is always designed around the real-world source of leakage — by patient, batch, or time — never a plain random shuffle.
Both. Full training scripts, configuration files and every relevant checkpointed weight transfer to you at the end of the engagement.
Explore related work
Explainable AI Systems
Making the model you validated explainable to the people who have to trust it.
View OPSMLOps for Regulated Environments
Getting a validated model into production with the audit trail regulators expect.
View AIApplied AI overview
See how model development fits into the full Applied AI service.
ViewHave a model you can’t fully trust yet?
Send us the data and the decision it needs to support — we’ll tell you honestly whether the model is ready, and what it would take to get it there.