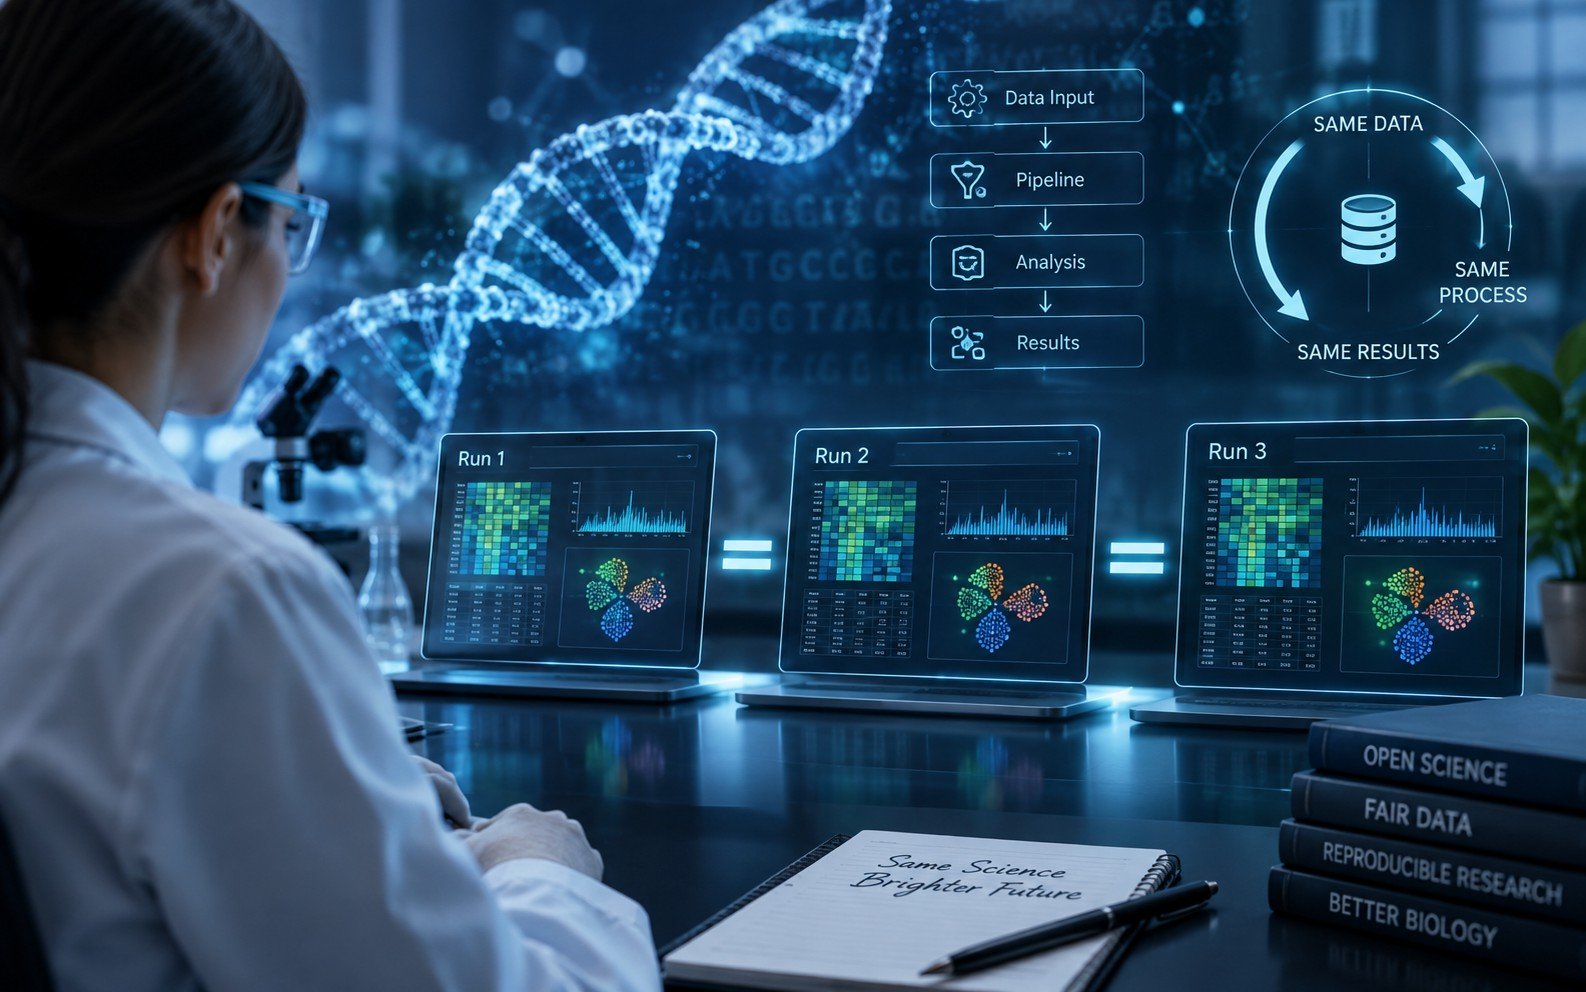
Every bioinformatics pipeline we’ve ever inherited from another team has passed its own tests. That’s rarely the problem. The problem shows up six months later, when someone reruns the same pipeline on the same data and gets a different answer — and nobody can explain why.
The reproducibility crisis nobody budgets for
Reproducibility failures in bioinformatics are almost never dramatic. They’re quiet: a reference genome that got silently updated, a tool version that changed its default parameters in a minor release, a manual step someone forgot was manual. Individually, each of these looks trivial. Compounded across a pipeline with a dozen stages, they add up to results nobody can fully stand behind.
The cost isn’t abstract. We’ve seen a peer reviewer reject a paper because the described pipeline couldn’t be reproduced from the methods section. We’ve seen a clinical program lose weeks re-validating results after a routine environment update. Reproducibility isn’t a nice property to have — it’s the thing that determines whether your result is science or anecdote.
Three failure modes we see constantly
- Unpinned dependencies. A pipeline that installs “the latest” version of a tool at runtime will eventually produce a different result than it did last year, with no warning.
- Undocumented reference data versions. Genome builds, annotation sets and databases update. If the version isn’t locked and recorded, two runs six months apart aren’t comparable, even if the code hasn’t changed.
- Manual steps disguised as automation. A pipeline that’s 95% scripted and 5% “then copy this file over and rename it” is not a reproducible pipeline — it’s a script with a manual failure point built in.
We stopped asking whether a result was reproducible. With a pipeline built the right way, it just is.
What we build differently
Every pipeline we deliver is containerized, with dependencies and reference data versions locked and recorded alongside the code. We treat the container definition as part of the deliverable, not an implementation detail. Runs are validated against known-answer or reference samples before they’re trusted in production, and every output carries enough metadata to trace it back to the exact code, container and input version that produced it.
None of this is exotic. It’s the same discipline software engineering has applied to deployments for a decade, applied to scientific pipelines where the stakes of an unreproducible result are considerably higher than a broken web page.