A company built at the intersection of the lab bench and the codebase.
Nuclyra exists to bridge the gap between biological science and software engineering. We build computational systems for teams that need both scientific depth and production-grade technology.
Founded to end the handoff problem.
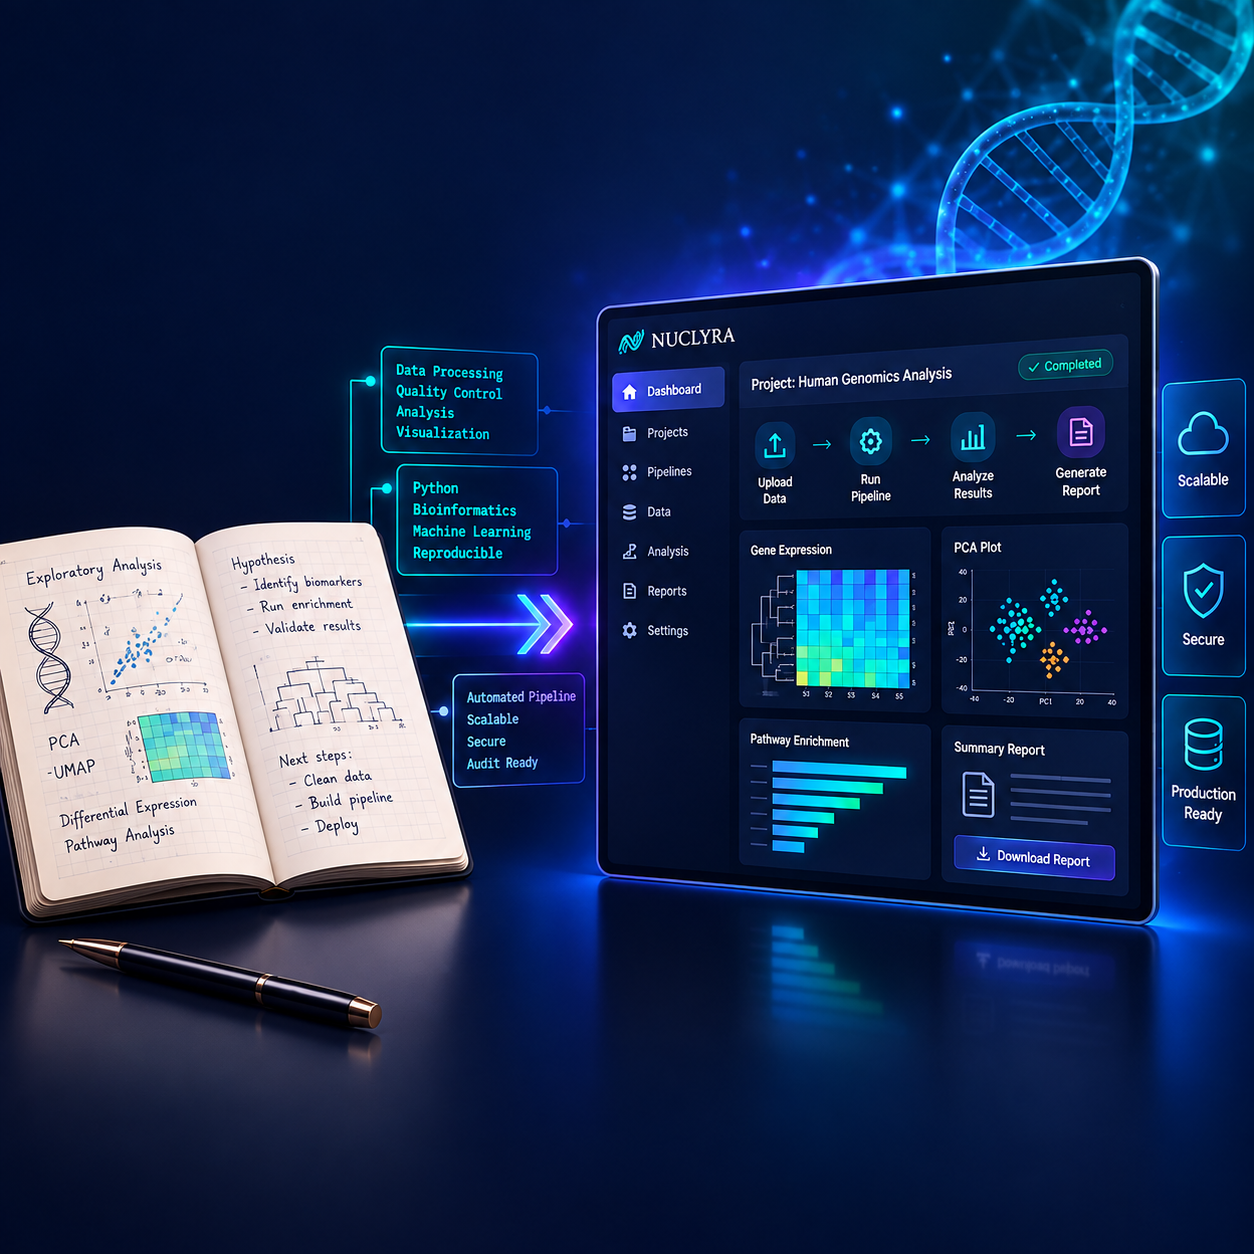
Nuclyra started as a small team of computational biologists and software engineers who kept seeing the same failure mode: a research group would build a brilliant analysis in a notebook, only to lose months translating it into something reproducible, secure, and scalable.
We built Nuclyra to remove that translation layer entirely—one team fluent in both Python and biology, from the first exploratory script to a production pipeline built for reproducibility, security, and audit readiness.
The north star, and the job that gets us there.
Two different time horizons. Both non–negotiable.
A world where scientific breakthroughs move from bench to real-world impact without losing their integrity in translation.
We want computational rigor to be the reason great science reaches patients, regulators and the public faster — never the reason it stalls in someone’s laptop.
Give life-science teams the computational backbone to spend their time on the science, not the plumbing.
Reproducible pipelines, secure infrastructure and applied AI — built by people fluent in both biology and code, and still in the room when it matters.
Six principles that don't change, project to project.
Curiosity
We stay students of the science. Asking the naive question is usually how the real bug gets found.
Integrity
We say what we can’t do as clearly and as early as what we can. No quiet scope creep, no dressed-up results.
Craft
We obsess over the parts of the pipeline no one else will ever notice — because eventually, someone always does.
Ownership
Every engagement is treated like our own product, not a ticket to close. If it breaks at 2am, we want the pager.
Empathy
We build for the researcher up against a grant deadline, not for a demo. That changes what we choose to prioritize.
Rigor
Data over opinion, always — including about our own work. If it isn’t validated, it isn’t done.
We didn’t want to be the vendor who hands back a black box. We wanted to be the team still in the room when the paper gets published.
Four commitments that shape every engagement.
Scientific fidelity first
Pipelines and models are validated against relevant biological or chemical ground truth wherever available—not just unit-tested against synthetic data.
Reproducibility by default
Versioned data, versioned environments, versioned models. If a result can’t be regenerated months later, we consider the job unfinished.
Security is not a phase
Access control, audit logging and compliance considerations are designed in from the architecture stage — especially for systems touching patient or genomic data.
Transparent collaboration
We design systems for portability and transparency, with clear documentation and access to the artifacts your team needs.
How an engagement typically runs.
Four stages, designed to surface risk early and keep scientific stakeholders in the loop throughout.
Scope the science
We sit with your researchers to map data sources, assay design and success criteria before writing a line of code.
Architect the system
Pipeline, model or platform architecture is proposed and stress-tested against edge cases in your domain.
Ship in increments
Working software is delivered incrementally and validated against real datasets at every milestone.
Document & transfer
Production deployment, documentation, validation, and knowledge transfer so your team can operate and extend the system independently.
Heard directly from the teams we work with.
Nuclyra didn’t just deliver a pipeline — they left us with a team that actually understands it. A year and a half later, we’ve extended it ourselves twice without calling them.
We came to them after a compliance audit flagged a black-box model. They rebuilt it as something we could actually explain to a regulator — and to ourselves.
Grant-cycle budgets are brutal for most vendors. Nuclyra was the first team that scoped its engagement around our funding cycle instead of the other way around.
Forty independent labs, one dataset, and nobody had to give up control of their own data. I still don’t fully understand how they pulled that off, but our consortium runs on it now.
They were the only computational partner we didn’t have to re-explain our program to when we moved from discovery into IND-enabling studies.
As a two-person technical team, Nuclyra effectively became our computational department for a year. Investors didn’t blink at our infrastructure during diligence.
Curious how we’d approach your project?
Send over your data problem — we’ll come back with a point of view, not just a proposal.