Notes from inside the engagements.
Field notes on bioinformatics, applied AI, compliance and the decisions that hold up once a system reaches production — written by the team doing the work.
Why Reproducibility Matters in Bioinformatics Pipelines
A pipeline that gives a different answer depending on who runs it isn’t a scientific tool. Here’s how we treat reproducibility as a hard requirement, not an aspiration.
Read the article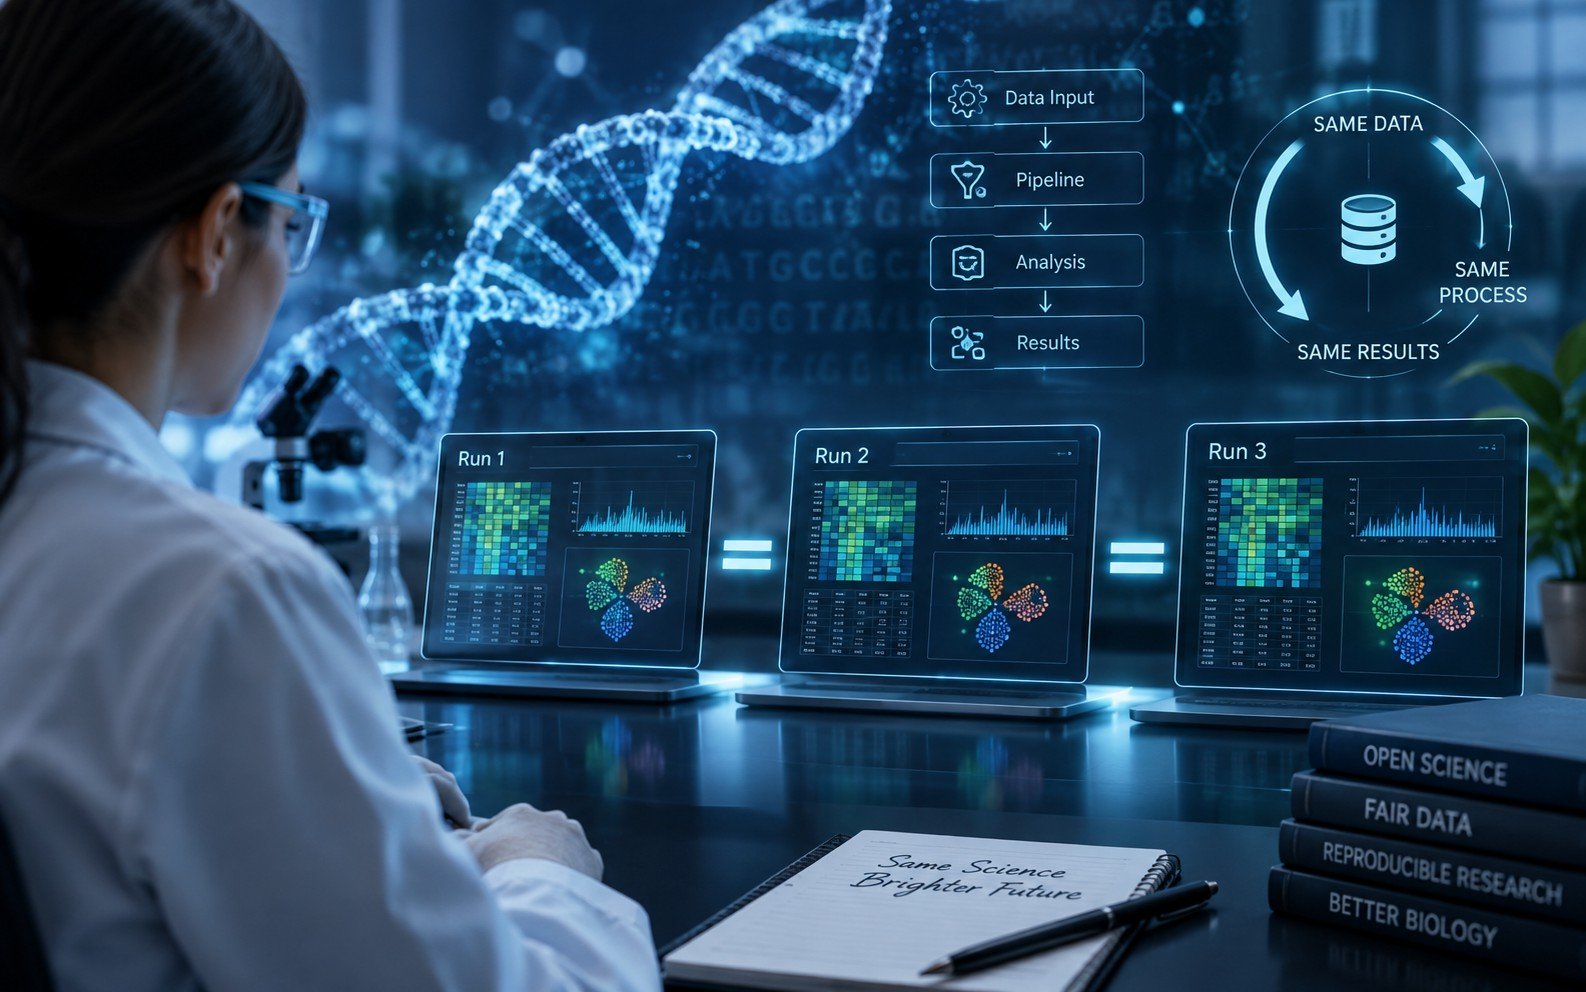
Every post, filtered your way.
Click a category to narrow the list. Every post also carries specific topic tags.

Why a Top BLAST Hit Isn’t a Species Identification
DNA barcoding can identify a species from a scrap of tissue — but a best match against a public database is not the same as a defensible identification. Here’s what separates the two.
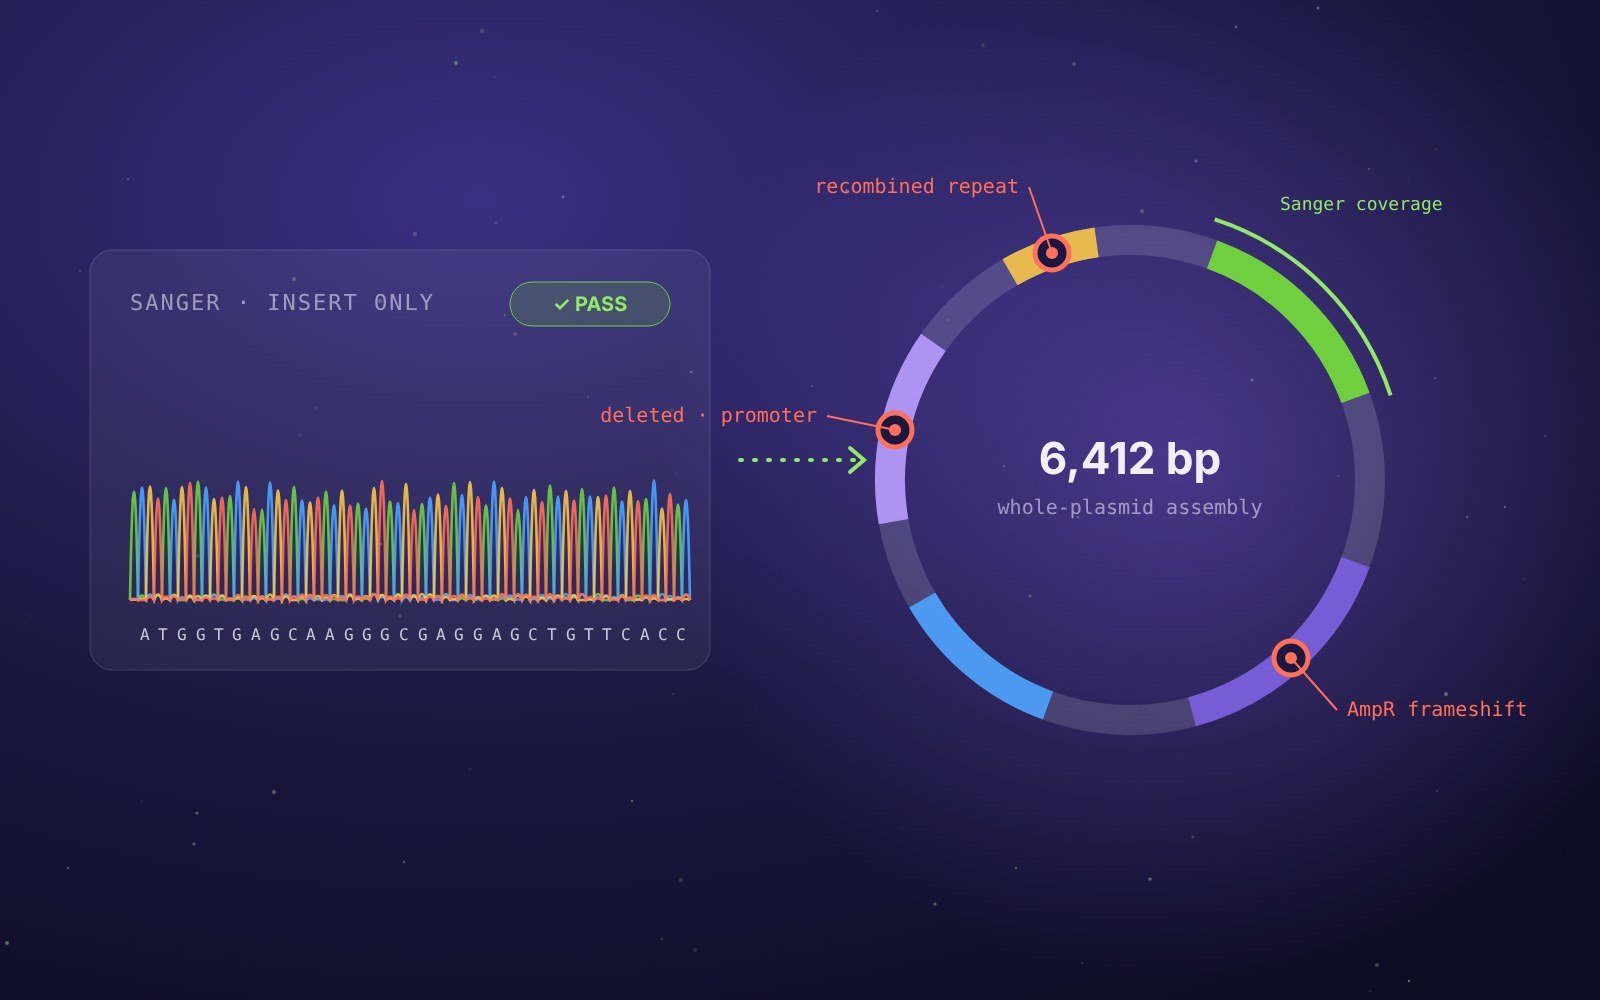
Your Sanger Trace Is Clean. Is Your Plasmid?
Sequencing a whole plasmid now costs about the same as a few Sanger reads. What it can catch — and what a verification pipeline has to get right — is a different story.

Five Questions to Ask Before You Trust an AI Model With Biological Data
A model with 95% accuracy on a holdout set can still be dangerously wrong in production. Here’s what we ask before we trust one.

Inside a Federated Genomics Platform: Lessons From a 40-Lab Consortium
Forty independent labs, one dataset, zero centralized raw data. Here’s what we learned building a federated genomics platform at that scale.

Security Isn’t a Phase: Designing Access Control for Genomic Data From Day One
Retrofitting access control onto a genomic data platform is slower and riskier than building it in from the schema up. Here’s our approach.
Have a problem that belongs in a future post?
The engagements we write about all started as a message like the one you’re about to send.